
Generative artificial intelligence is no longer limited to chatbots such as ChatGPT. Today, it is integrated directly into business software, ERP and CRM systems, web applications, development tools, and automation platforms.
This integration is typically enabled by a generative AI API, which allows software to interact with an AI model to generate text, analyse documents, write code, understand images, or automate tasks.
While cloud APIs from OpenAI, Anthropic, Google Gemini, and Mistral AI have made these use cases widely accessible, they raise two major concerns for businesses: data confidentiality and cost control. This is precisely why local, on-premise generative AI APIs are gaining momentum.
What Is a Generative AI API?
A generative AI API is an interface that enables software to communicate with an artificial intelligence model. Rather than interacting with a chatbot, an application sends a request directly to a model and retrieves its response for automated use.
This approach embeds artificial intelligence at the core of business processes. An application can automatically summarise a document, analyse a contract, draft a customer reply, generate code, transcribe an audio recording, or search through thousands of documents using embeddings.
Generative AI then becomes a genuine software component, operating seamlessly in the background for users.
Cloud AI APIs Have Two Important Limitations
Cloud AI APIs have significantly accelerated the adoption of artificial intelligence in business. They are easy to integrate and provide access to high-performing models with just a few lines of code.
However, this simplicity comes with two constraints that quickly become critical as AI use cases scale: data leaves the company, and every API call is billed according to the number of tokens consumed.
Data Confidentiality: An Often Underestimated Challenge
Most companies are now aware of the risks associated with Shadow AI. They understand that an employee who copies a contract, confidential document, or source code into a public chatbot may put sensitive information at risk.
However, many organisations do not realise that the same issues arise when they use a cloud AI API.
The process is essentially the same: data is sent to external infrastructure for the model to process it before a response is returned. This data may include contracts, quotations, customer files, financial documents, HR data, medical records, source code, or strategically important industrial information.
Even when an AI provider applies robust security measures or contractually commits not to use certain data to train its models, that information still leaves the company’s information system.
For many organisations—particularly in the public sector, industry, legal services, healthcare, or defence—this external transfer of data is already a problem. Digital sovereignty requirements, internal security policies, and regulatory obligations may require data processing to remain entirely within the company’s own infrastructure.
A Local AI API Ensures Data Sovereignty
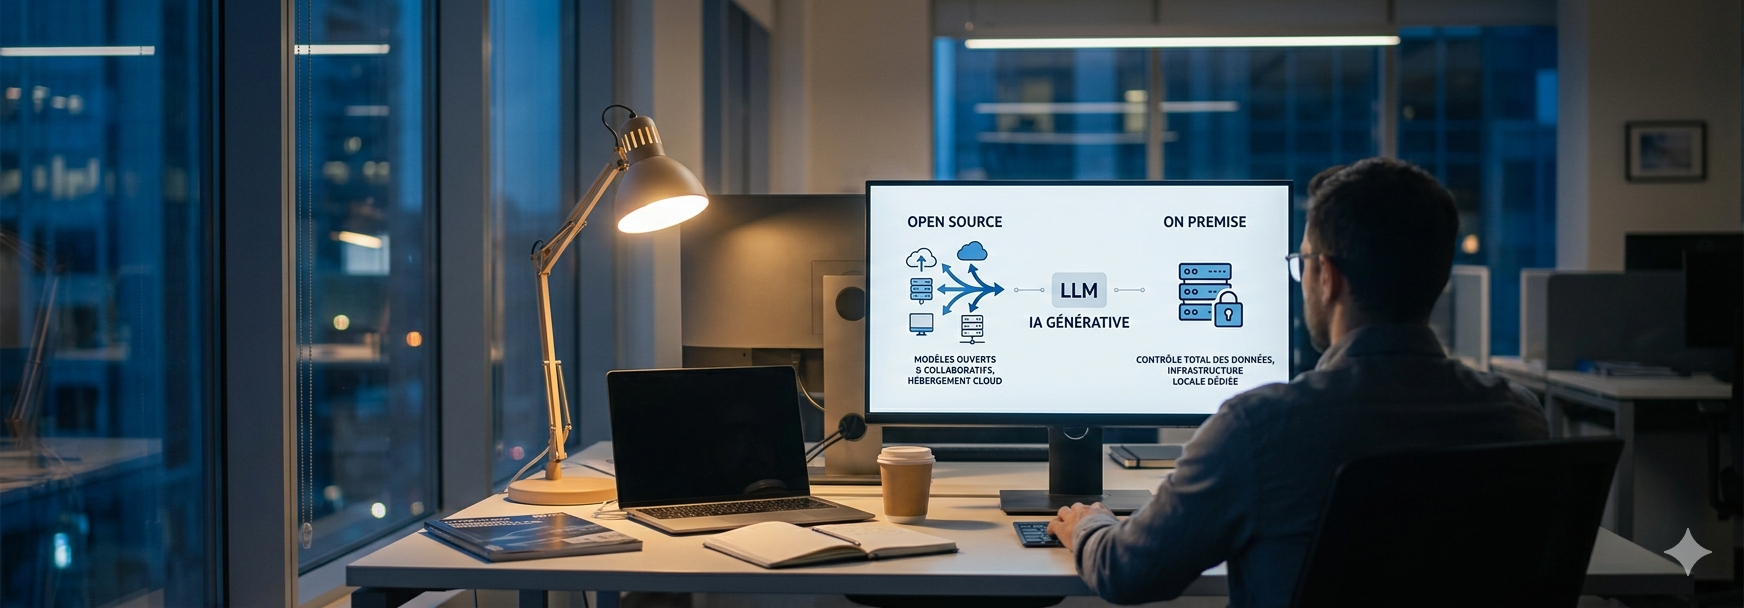
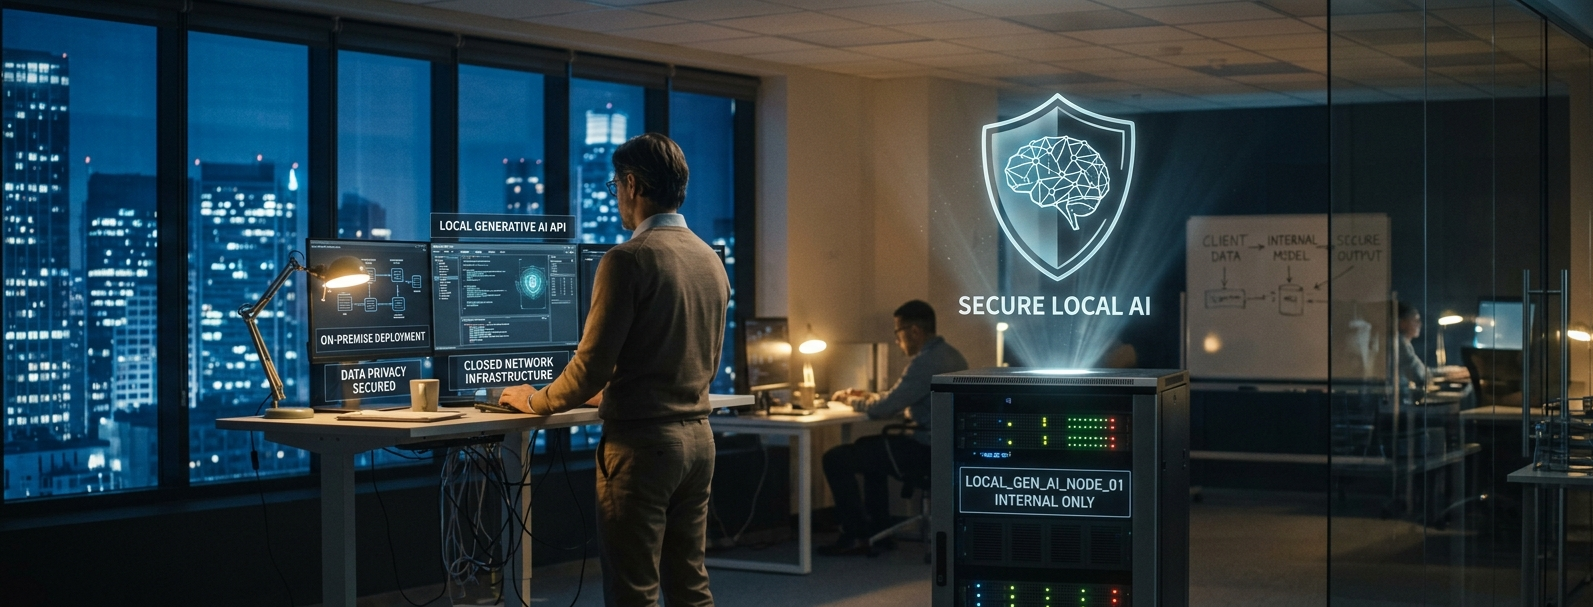
An on-premise generative AI API takes a fundamentally different approach. AI models are installed directly on a server owned or controlled by the company.
All requests remain within the internal network, and no information is transmitted to an external provider. Employees can analyse confidential documents, develop code, process financial data, or automate sensitive workflows while retaining full control over the information being handled.
This architecture also makes it easier to meet compliance requirements while significantly reducing the risks associated with data transfers.
Cloud AI API Costs Increase With Usage
The second major challenge is pricing. Most cloud AI APIs use a token-based billing model. Every prompt sent to the model and every generated response is converted into tokens, which are then billed.
Costs depend on several factors:
- Number of users
- Volume of requests
- Prompt size
- Length of generated responses
- Number of documents analysed
- Continuous automated processes
This model works well for early experiments, but it becomes much more difficult to control when artificial intelligence is integrated into several business applications or used daily by hundreds of employees.
Some large companies have found that their AI API spending increased much faster than expected. Uber, for example, has indicated that widespread adoption of generative AI exceeded the budgets initially anticipated for AI services, illustrating how difficult it can be to forecast fully consumption-based costs.
A Local AI API Provides Long-Term Cost Control
With a local AI API, this pricing logic disappears. Because models run directly on the company’s servers, there is no token-based billing.
Costs primarily consist of IT infrastructure, electricity consumption, and standard maintenance expenses. This delivers much stronger budget visibility.
A company can connect as many applications as it needs, develop new use cases, or significantly increase the number of users without seeing its bill rise proportionally with every request. Once the infrastructure is properly sized, operating costs become far more predictable.
Local AI APIs Support the Same Use Cases as Cloud APIs
One of the most common misconceptions is that a local AI API is less powerful or more limited than a cloud API. In reality, the open-source models available today cover virtually every business need.
A local AI API can integrate different types of models, including:
- Large language models (LLMs)
- Reasoning models
- Software development models
- Vision models
- Speech-to-text models
- Text-to-speech models
- Embedding models
- OCR models
- Industry-specific models
Businesses can choose the most effective models for their needs, upgrade them over time, and benefit from the latest advances in the open-source ecosystem without becoming dependent on a single provider.
In practical terms, a local AI API can assist developers directly in Visual Studio Code, Claude Code, or Cursor without any source code leaving the company. It can also power n8n automations to generate contracts, quotations, invoices, meeting summaries, tender responses, or administrative letters automatically.
It can analyse thousands of internal documents through embeddings, power a RAG system, extract information from invoices or forms, understand images, and transcribe meetings.
In practice, the capabilities of a local AI API are now comparable to those of a cloud AI API—while keeping data inside the company.
Artemia Supports the Deployment of Your Local Generative AI API
At Artemia, we support businesses that want to industrialise their artificial intelligence use cases while maintaining full control over their data and costs.
Our approach always begins with an analysis of your use cases. We work with clients to identify the processes they want to automate, the expected performance levels, and the technical constraints of their environment.
We then select the most suitable AI models—whether language, reasoning, vision, software development, embedding, or speech-recognition models—and design a tailored AI API.
The API is deployed directly on a server within the client’s infrastructure. It can connect to ERP systems, CRM platforms, business applications, development environments, automation platforms such as n8n, or any other application that uses a generative AI API.
The result is a fully local solution that is compatible with market standards, protects sensitive data, and provides stable operating costs without token-based billing.